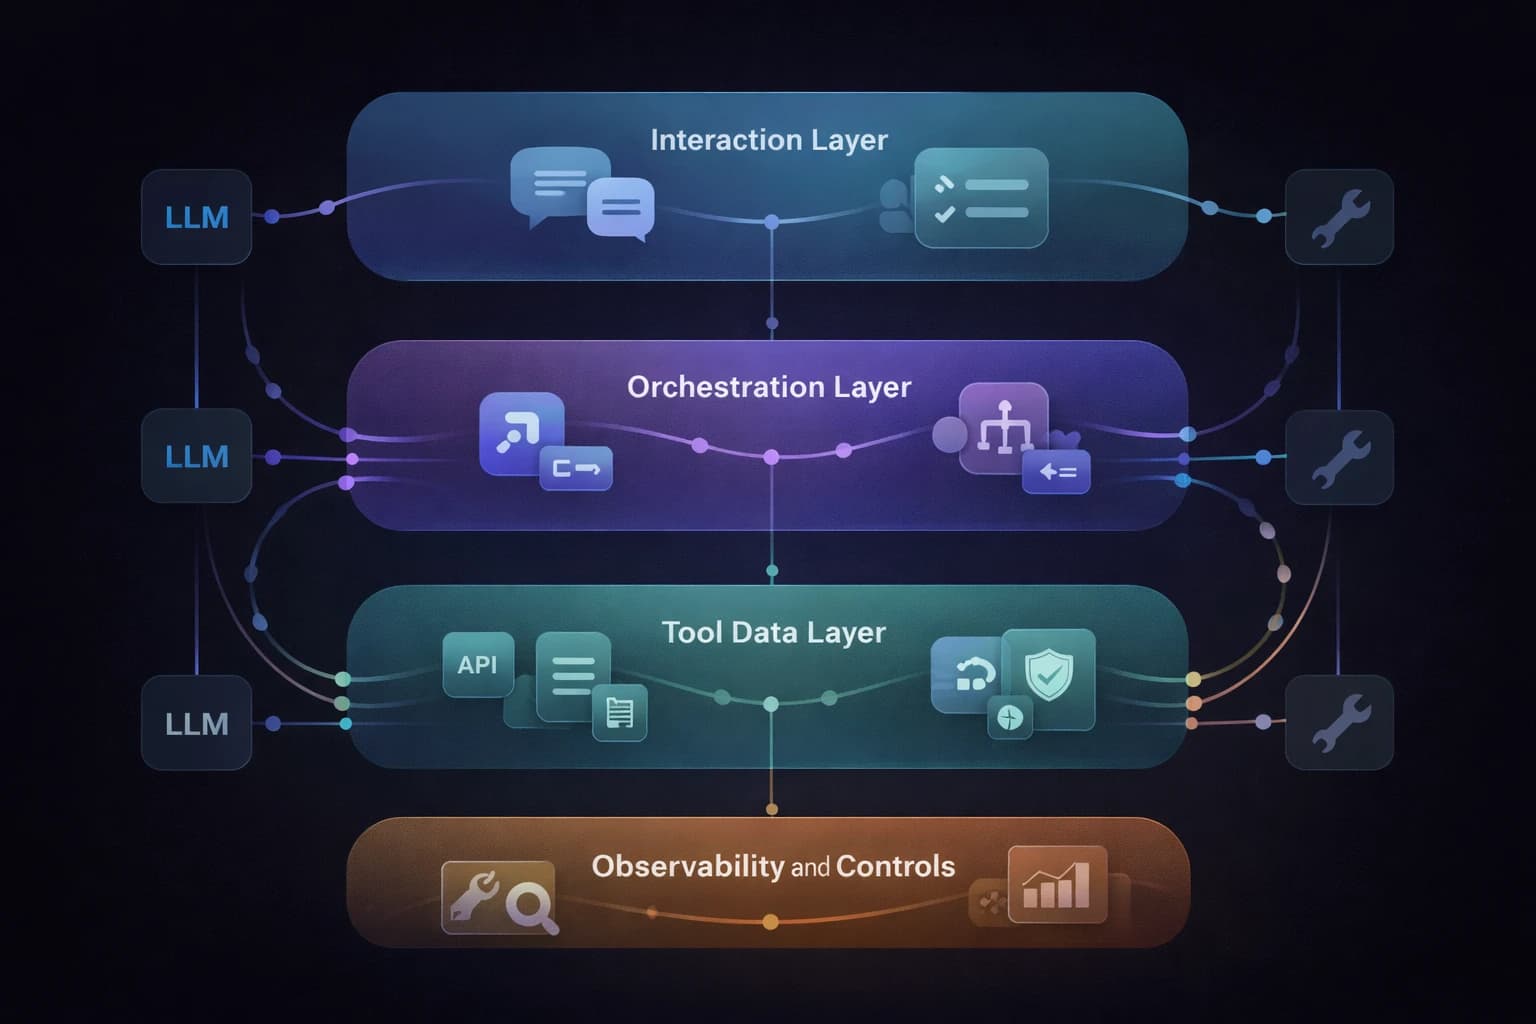
The Startup Agent Stack in 2026: What to Build and What to Skip
A founder-friendly breakdown of the modern AI agent stack and the minimum architecture needed to launch reliable agent workflows.
Read articleA practical framework to manage LLM cost, latency, and quality without slowing product delivery.
AI features can improve conversion and retention.
But without clear constraints, usage grows quickly and costs follow.
For startups, this creates pressure before unit economics are fully understood.
LLM cost is not just a finance concern.
It is a product and engineering design decision.
Costs behave differently across workflows. Treat them that way.
Not every request needs the best model.
Small reductions compound quickly at scale.
Good UX can reduce cost without hurting experience.
Visibility enables better tradeoffs.
The goal is not maximum model performance.
The goal is value per dollar.
If you need help scaling AI features with tighter cost controls,
Share this article
Michael G
Founder (Product & Engineering)
Founder-led product engineering focused on fast execution and measurable outcomes.

Qodeware Editorial
Editorial Team
Insights from the Qodeware team on product strategy, engineering, and AI-native delivery.
A founder-friendly breakdown of the modern AI agent stack and the minimum architecture needed to launch reliable agent workflows.
Read article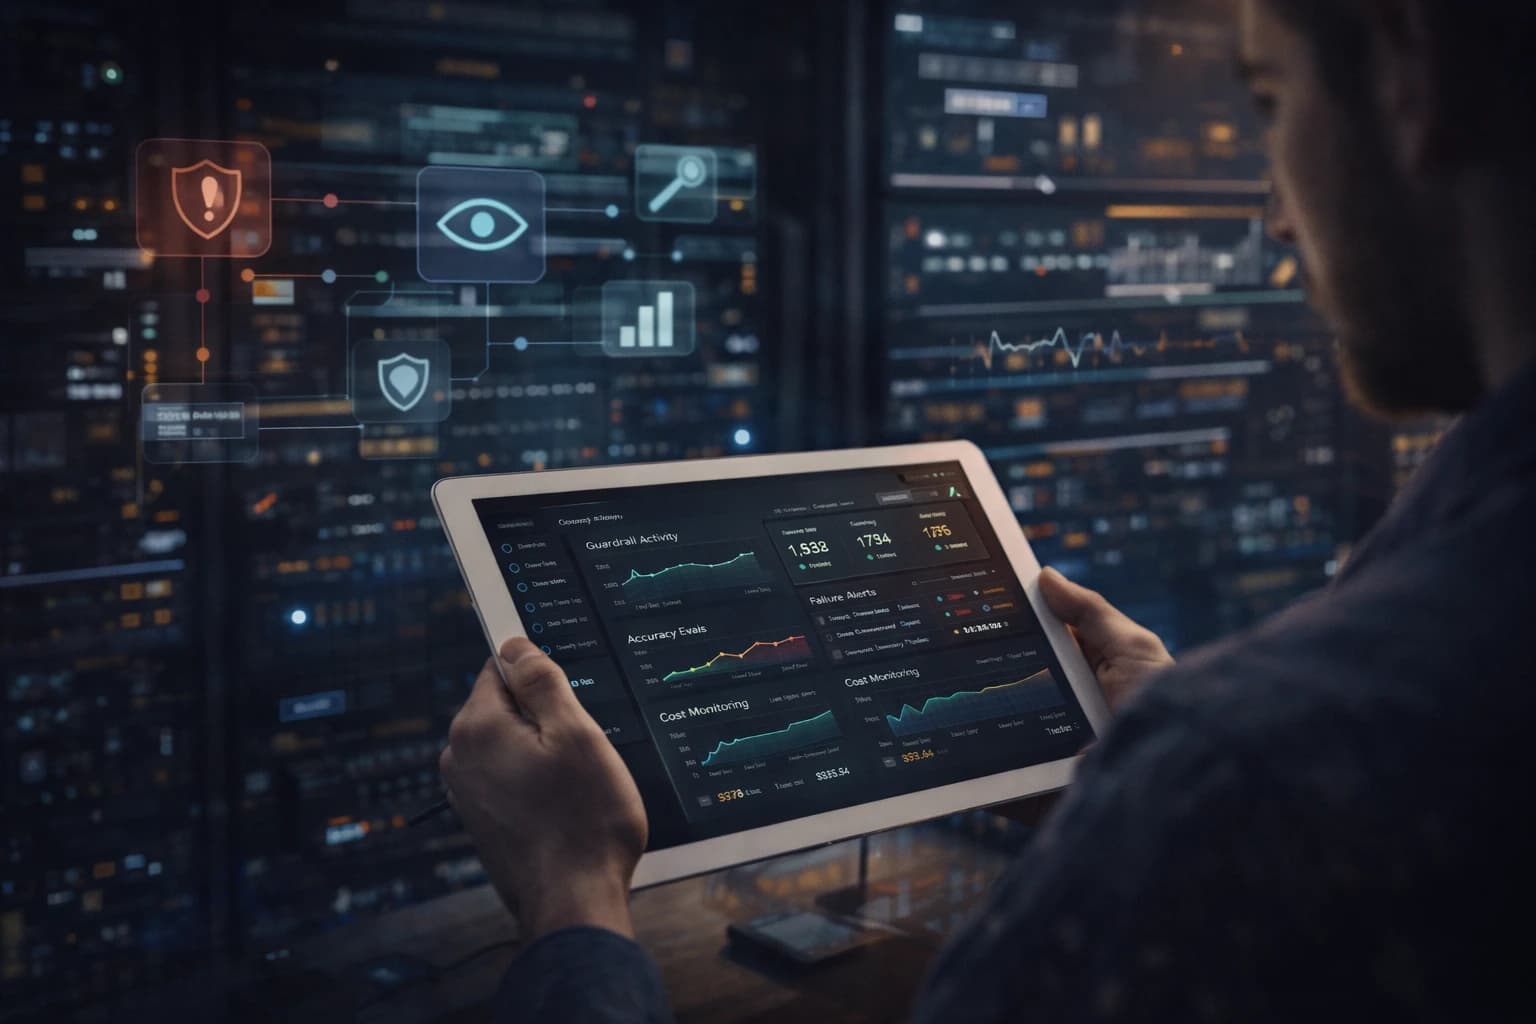
A production playbook for AI products covering guardrails, evaluation loops, and observability patterns that reduce launch risk.
Read article
A practical operating rhythm founders can use to keep teams aligned, shipping, and accountable from scope to launch.
Read articleBook a focused call and we can map scope, delivery approach, and execution plan.